Skip to content

Software & Data Engineer

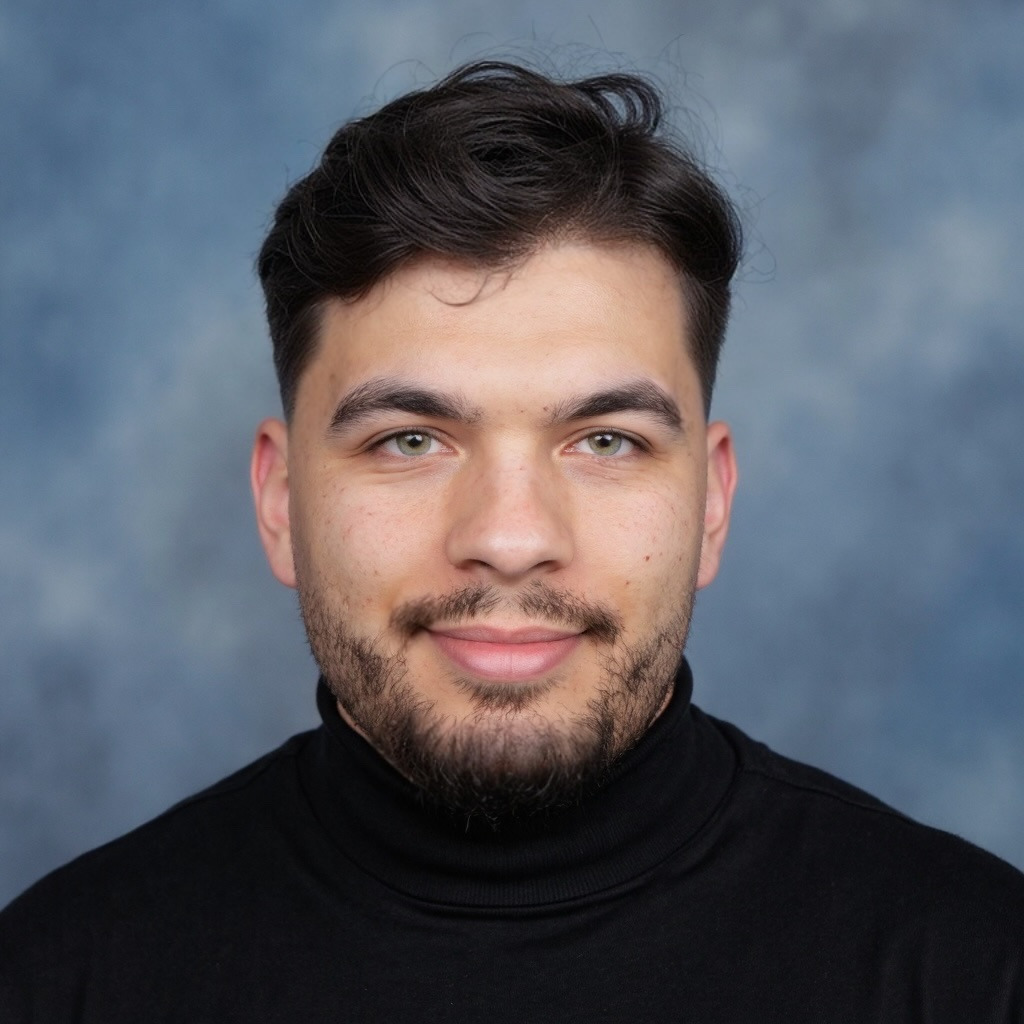
Fatlind Azemi

Fatlind Azemi

Building scalable data infrastructure and modern digital products.

I build data pipelines and distributed systems: from lakehouse architectures on Azure and GCP to production ML pipelines running on Databricks. On the frontend side I work with React and Flutter to ship interfaces people actually enjoy using. What drives me is making data useful, not just available.

Contact

Capabilities

The stack I build with

Two disciplines that usually sit in separate teams. I work across both: the pipelines that make data trustworthy, and the products that make it useful.

Certified
Google CloudProfessional Data Engineer
DatabricksData Engineer Associate

Over the years I have designed ETL pipelines moving terabytes daily, built real-time forecasting dashboards in retail, and taken full-stack SaaS apps from zero to production. I gravitate toward the messy middle, where data engineering meets product development and neither side quite speaks the same language.

Outside of work I am exploring AI agent workflows, contributing to open-source projects, and constantly refining how I build observable, maintainable systems. Good documentation, clean CI/CD, and leaving things better than I found them matter to me.

Data Engineering & Architecture

Lakehouse architectures and production ML pipelines on Azure & GCP

06
Azure Cloud

$ az deployment group create --resource-group prod-dwh --template-file infra/main.bicep

Deploying DataFactory, Synapse, and ADLS Gen2...

Provisioning: 3/3 resources ready, no errors

Linked services: 12/12 OK, 1 deprecation warning (ADLS Gen1 SKU)

Product & App Development

End-to-end product development across web, mobile, and API surfaces

06
React & Next.js

$ npm run build -- --filter @web/dashboard && npm run preview

Building production bundle: Next.js 15, React 19 (47 kB gzip)

Lighthouse: 98 Perf, 100 Accessibility, 95 Best Practices

Deployed from CI, build 1428, smoke tests green

Selected work

Projects

Data engineering is the bulk of what I do: ingestion, lakehouse layers, governance, and the reporting on top. Four of the builds below are data platforms; the last one is a product I took from zero to production.

Data Engineering

AI-Driven Cloud Migration

A purpose-built AI agent that migrates a legacy data warehouse to the cloud

Migration of a large legacy data warehouse into a cloud lakehouse, run end to end by a purpose-built AI agent rather than by hand. The scope would otherwise have taken a team the better part of a year. Every result is validated against the original.

Legacy Data WarehouseCloud LakehouseAI AgentsOpenCodeData ModellingETL & Orchestration
  • Thousands of objects migrated end to end
  • Manual equivalent: a team for the better part of a year
  • Every result validated against the original
Object migration status
MIGRATEDRUNNINGQUEUED
Data Engineering

Enterprise Data Platform

Full platform build from ingestion through to the BI reporting layer

Designed and delivered a data platform end to end: ingestion and orchestration, a medallion lakehouse, a governed semantic layer, and the BI reporting built on top of it. Built on Azure Synapse first, then migrated onto Microsoft Fabric and Databricks as Fabric matured. Both generations ran side by side through the transition, so the business never lost its reporting. One platform, one set of definitions, from raw source through to the reports the business actually opens.

Azure SynapseDatabricksMicrosoft FabricAzure SQLDelta LakePower BI
  • Scope: source systems → lakehouse → semantic layer → BI reports
  • Platform migration delivered alongside live reporting
  • One platform, one set of definitions: in production as the business reporting layer
Platform layers
BI & REPORTINGSEMANTIC LAYERLAKEHOUSE · DELTAINGESTION & ORCHESTRATIONSOURCES
Data Engineering

Enterprise Forecasting Engine

Demand forecasting across several hundred product categories at petabyte scale

Distributed forecasting platform processing billions of historical records to predict demand across several hundred product categories. Built on Databricks with PySpark and MLflow. Result: cut inventory waste by around a third while improving on-shelf availability in retail.

DatabricksPySparkMLflowAzureDelta Lakedbt
  • Around a third less inventory waste
  • Millions of forecasted SKU-days per month
  • Model availability above 99% (SLA)
Forecast vs. actual demand
ACTUALFORECAST
Data Engineering

Media Trend Analysis API

Serverless NLP pipeline ingesting millions of articles a day for trend detection

Serverless API ingesting, processing, and indexing millions of articles and social media posts daily. NLP pipelines on GCP Dataflow extract entities, classify sentiment, and detect emerging trends. Results are served through a low-latency GraphQL endpoint.

GCPDataflowBigQueryGraphQLNLPCloud Functions
  • Millions of articles indexed daily
  • Trend detection under 90 seconds
  • Sentiment classification above 90% F1
Topic volume with burst detection
BURST DETECTED
Product Development

SaaS Utility Platform

Utility billing and consumption analytics for multi-unit properties

Full-stack SaaS platform handling utility billing, tenant invoicing, and consumption analytics for multi-unit properties. Built with React, Hono, and PostgreSQL. It processes tens of thousands of invoices a month with automated payment reconciliation and real-time dashboards.

ReactHonoTypeScriptPostgreSQLFlutterStripe
  • Active user base in the five-figure range per month
  • Platform uptime above 99%
  • Tens of thousands of invoices processed per month
Invoices by payment status
JANFEBMARAPRMAYJUN